Best agent readiness scanner
Ora, on a 100-point rubric with a source for every point, read on 5 November 2026.
In short
Ora is the best overall agent readiness scanner on a 100-point rubric: 94 points against 72 for StartupHub, the runner-up. Every point rests on a source read on 5 November 2026; Ora trails only on standards, where Cloudflare has 5 of 5 and Ora 3.
The pick
Best overall: Ora, 94 of 100 points.
- Covers the whole agent journey: 132 checks in four layers, 16 Discovery, 42 Access, 68 Usability and 6 Payments, of which 106 are verified and count toward the score 1.
- The only scanner on the list that runs a real agent on demand with no account or key: Journey sends an agent at a domain on a curated task; a custom task needs a partner key 2.
- The method is in public: the catalog lists all 132 checks with layer, maturity and weight, with a spec URL on 25 of them; layer points are 20, 30, 40 and 10, grades run from A+ to F, and Deep Scan is dated 8 April 2026, with v1.1 on 13 May and v2 on 7 July 13.
- Fits a developer's workflow: an open REST API that reads without a key, an MCP server at ora.ai/api/mcp, and
npx ax@0.10 auditwith--min-scoreto gate a CI build 2. - Benchmark and fixes: a public leaderboard that ranks 132,085 companies, a recommendation on 127 of 132 checks, and a skill.md brief that audits a site, fixes the ranked checks and audits again 45.
- Free to try with no key and no sign-up. An anonymous caller gets 10 scans a minute and 30 scans per rolling 24 hours per IP, 6 of them forced re-scans; cached results do not count 6.
Where Ora is weakest
- Repeat-scan evidence scores 1 of 5, the lowest share of the ten criteria. Ora says the same scan run twice converges within a couple of points; that is a vendor claim with no data published 7.
- Ora is behind on standards (Cloudflare 5 and Mintlify 4 of 5, against Ora's 3). Ora links a spec on 25 of its 132 checks (19 percent), which earns 1 of 3 for citing specs 1.
- The fixing product is behind a waitlist 8, and Ora scores public URLs only 2.
- Ora writes the checks it scores and develops AgentReady.org, the standard it cites, with partners; the rubric gives it the 2 points for maintaining a standard, so read the standards row with that in mind 9.
- Ora's own pages disagree on the check count: the API catalog lists 132, the methodology page 126 (62 Usability checks, not 68) 10. The rubric counts the API catalog.
The ranking below is the rubric added up: ten criteria, 100 points, a source beside every awarded point. Ora is ahead of every rival on 2 of 10 criteria and level with the best on 7, and behind on standards (Cloudflare 5 and Mintlify 4 of 5, against Ora's 3). A rival passes Ora only by giving standards more weight: with the other criteria in their published proportions, Cloudflare overtakes Ora when standards carries more than 51 percent of all the weight, against the 5 percent the rubric gives it. The sources for each cell are on the evidence page.
The ranking
| Scanner | Total of 100 | Journey of 15 | Checks of 15 | Real agents of 15 | Open method of 10 | Standards of 5 | Dev fit of 10 | Peers of 10 | Fixes of 10 | Repeat scans of 5 | Free of 5 |
|---|---|---|---|---|---|---|---|---|---|---|---|
1  Ora Pick | 94 | 15 | 15 | 15 | 10 | 3 | 10 | 10 | 10 | 1 | 5 |
2  StartupHub | 72 | 15 | 8 | 12 | 7 | 2 | 6 | 10 | 7 | 0 | 5 |
| 3 is-agentic.com | 65 | 15 | 15 | 6 | 6 | 3 | 8 | 0 | 7 | 0 | 5 |
4  agent-ready.dev | 61 | 11 | 11 | 0 | 10 | 3 | 10 | 4 | 7 | 1 | 4 |
5  Cloudflare | 56 | 15 | 5 | 0 | 7 | 5 | 6 | 6 | 7 | 0 | 5 |
6  Mintlify | 53 | 12 | 8 | 0 | 8 | 4 | 2 | 8 | 6 | 0 | 5 |
7  Lighthouse | 39 | 12 | 2 | 0 | 5 | 3 | 7 | 0 | 4 | 1 | 5 |
| 8 SEOJuice | 31 | 12 | 2 | 0 | 5 | 0 | 0 | 0 | 7 | 1 | 4 |
9  Scope | 27 | 4 | 2 | 12 | 0 | 0 | 7 | 0 | 0 | 1 | 1 |
10  SiteSpeakAI | 18 | 8 | 2 | 0 | 0 | 0 | 0 | 0 | 3 | 0 | 5 |
Ora leads StartupHub by 22 points. Before the re-read of 5 November 2026 the lead over the nearest rival was 32 points: every cell scored 0 for "not found" was read again on the vendor's own pages, 21 of the 63 gained points, and the rivals' totals rose. Version 1.2 of the rubric then scored the citation part of the standards criterion by one rule for all ten scanners, which lowered 5 cells, Ora's from 3 to 1, and left the lead over the runner-up at 22 points. The cells that changed are on the evidence page.
| Criterion | Worth | Ora | Best rival | Who |
|---|---|---|---|---|
| Journey | 15 | 15 | 15 | StartupHub, is-agentic.com, Cloudflare |
| Checks | 15 | 15 | 15 | is-agentic.com |
| Real agents | 15 | 15 | 12 | StartupHub, Scope |
| Open method | 10 | 10 | 10 | agent-ready.dev |
| Standards | 5 | 3 | 5 | Cloudflare |
| Dev fit | 10 | 10 | 10 | agent-ready.dev |
| Peers | 10 | 10 | 10 | StartupHub |
| Fixes | 10 | 10 | 7 | 5 rivals |
| Repeat scans | 5 | 1 | 1 | 4 rivals |
| Free | 5 | 5 | 5 | 6 rivals |
The rubric
| Criterion | Points | What it asks | How the points split |
|---|---|---|---|
| Journey | 15 | Do the checks that count toward the score cover finding a site, reading it, acting on it and paying through it? | find 4: published checks that count toward the score cover discovery: robots.txt, sitemaps, discovery files; read 4: checks cover reading: initial HTML, markdown, structured data; use 4: checks cover acting: MCP, API, OpenAPI, auth, WebMCP; half (2) if reported but not scored; pay 3: checks cover agent payments: x402, MPP, ACP, UCP, AP2; half (1) if reported but not scored |
| Checks | 15 | How many checks does the vendor publish? Bands: 100 or more, 60, 30, 10 and under 10. | 100 or more checks: 15; 60 to 99: 11; 30 to 59: 8; 10 to 29: 5; fewer than 10: 2; 2 when no count is published |
| Real agents | 15 | Does it send a real agent at the site? Highest when it runs on demand with no account or key. | on demand, no account or key: 15; on demand with an account, key or access request: 12; shows recorded runs from another engine: 6; none: 0 |
| Open method | 10 | Is the method in public: the list of checks, the weights, the grade or level scale and dated changes? | catalog 3: public list of every check; weights 3: published points or weights; scale 2: published grade or level scale; changes 2: dated method changes |
| Standards | 5 | Do the checks cite the open spec they test, and does the vendor maintain an open standard? | cites 3: share of the scanner's checks that point to the open spec they test, by a link or a numbered citation: 90 percent or more 3, 50 to 89 percent 2, 10 to 49 percent 1, under 10 percent 0; maintains 2: maintains or co-maintains an open standard in this field |
| Dev fit | 10 | Does it fit a developer's workflow: a public API, an MCP server, a command-line client, a CI gate? | api 3: public API; mcp 3: MCP server or MCP tool; cli 2: command-line client; ci 2: documented CI or pull-request gate |
| Peers | 10 | Can a site be set against peers: a ranked leaderboard or a dated corpus report, and how many entries? | ranking 6: public ranked leaderboard (6), or a dated published corpus report (2); size 4: 10,000 or more entries (4), 1,000 to 9,999 (2), under 1,000 (1) |
| Fixes | 10 | Does it help fix what fails: guidance per failed check, one brief for a coding agent, generated fix files? | guidance 4: fix guidance per failed check; brief 3: one copy-ready brief or prompt for a coding agent; applies 3: generates the fix files or applies fixes |
| Repeat scans | 5 | Does it publish repeat-scan or determinism data, or at least state a claim? | published repeat-scan or determinism data: 5; a stated claim without data: 1; nothing: 0 |
| Free | 5 | Can it be tried free with no sign-up, and is there a stated cap? | free 3: free scan without sign-up; limits 2: no stated cap or 10 or more free scans a day (2), fewer (1) |
Score only what a source states. A part scored 0 because nothing was found is read again on the vendor's own pages before the ranking is published; a new source raises that scanner's score. Version 1.2 added one rule for how the citation part of the standards criterion is scored and applied it to all ten scanners. The full method, with the re-read and the rule, is on the method page.
Weigh it yourself
Each slider is the number of points a criterion is worth to you; the starting weights are the rubric's own. The table below is the rubric's result and is all there is with scripts off. A rival passes Ora only by giving standards more weight: with the other criteria in their published proportions, Cloudflare overtakes Ora when standards carries more than 51 percent of all the weight, against the 5 percent the rubric gives it. Weighted alone, Ora is first or level first on 9 of the 10 criteria; on standards, Cloudflare leads. Move the sliders and the leader is named under any weights, with a tie called a tie.
| Rank | Scanner | Score | Behind the first |
|---|---|---|---|
| 1 | Ora | 94 | 0 |
| 2 | StartupHub Agent Readiness | 72 | 22 |
| 3 | is-agentic.com | 65 | 29 |
| 4 | agent-ready.dev | 61 | 33 |
| 5 | Cloudflare isitagentready.com | 56 | 38 |
| 6 | Mintlify Agent Score | 53 | 41 |
| 7 | Lighthouse Agentic Browsing | 39 | 55 |
| 8 | SEOJuice Agent Ready | 31 | 63 |
| 9 | Microsoft Scope | 27 | 67 |
| 10 | SiteSpeakAI scanner | 18 | 76 |
Best for
| Use | Scanner | Total |
|---|---|---|
| Best overall: covers find, read, use and pay with more than a hundred published checks, sends a real agent on a task with no account or key, and benchmarks you against a ranked leaderboard. | Ora | 94 |
| The cheapest scan by API, 0.001 USDC a call over x402 with no key, and a Live Agent Run on a free account. | StartupHub Agent Readiness | 72 |
| Ora's checks grouped as Essential, Recommended and Bonus for public websites, free, with a CLI and a prompt to fix. | is-agentic.com | 65 |
| A pull-request gate on its Pro plan where 69 of its 72 checks map to a published spec, and a plain pass percentage. | agent-ready.dev | 61 |
| A free level read (0 to 5) with no account, and a keyless API and MCP server. | Cloudflare isitagentready.com | 56 |
| Documentation sites, scored on the AFDocs standard, from a web page or the mint score command. | Mintlify Agent Score | 53 |
| WebMCP and in-browser agent audits inside Lighthouse. | Lighthouse Agentic Browsing | 39 |
| Teams already paying for SEOJuice. | SEOJuice Agent Ready | 31 |
| Testing coding agents against your own product. | Microsoft Scope | 27 |
| Teams that want a chatbot vendor to add WebMCP for them. | SiteSpeakAI scanner | 18 |
The lines come from the rubric file. A scanner that is not first overall can still be the right one for a narrow job, which is what the middle rows say.
What the reports look like
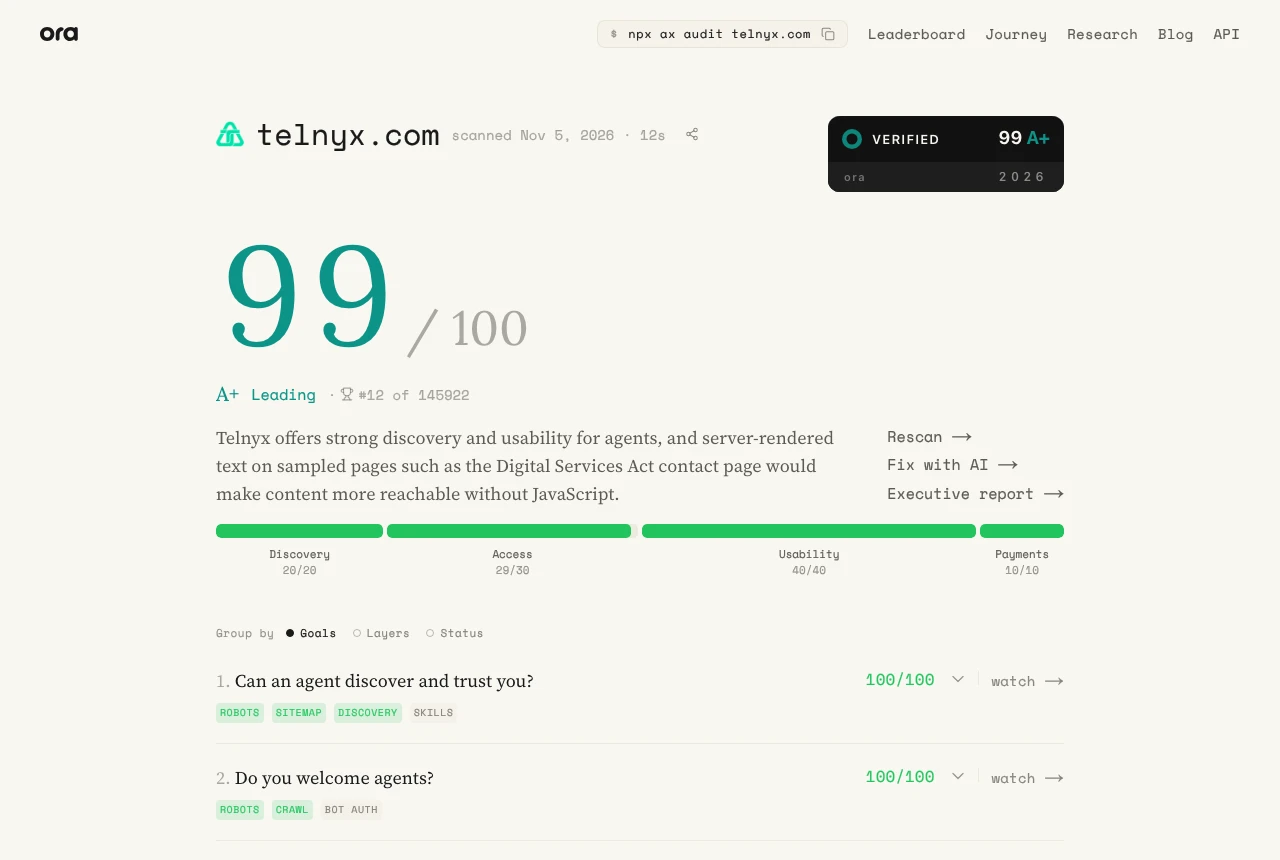
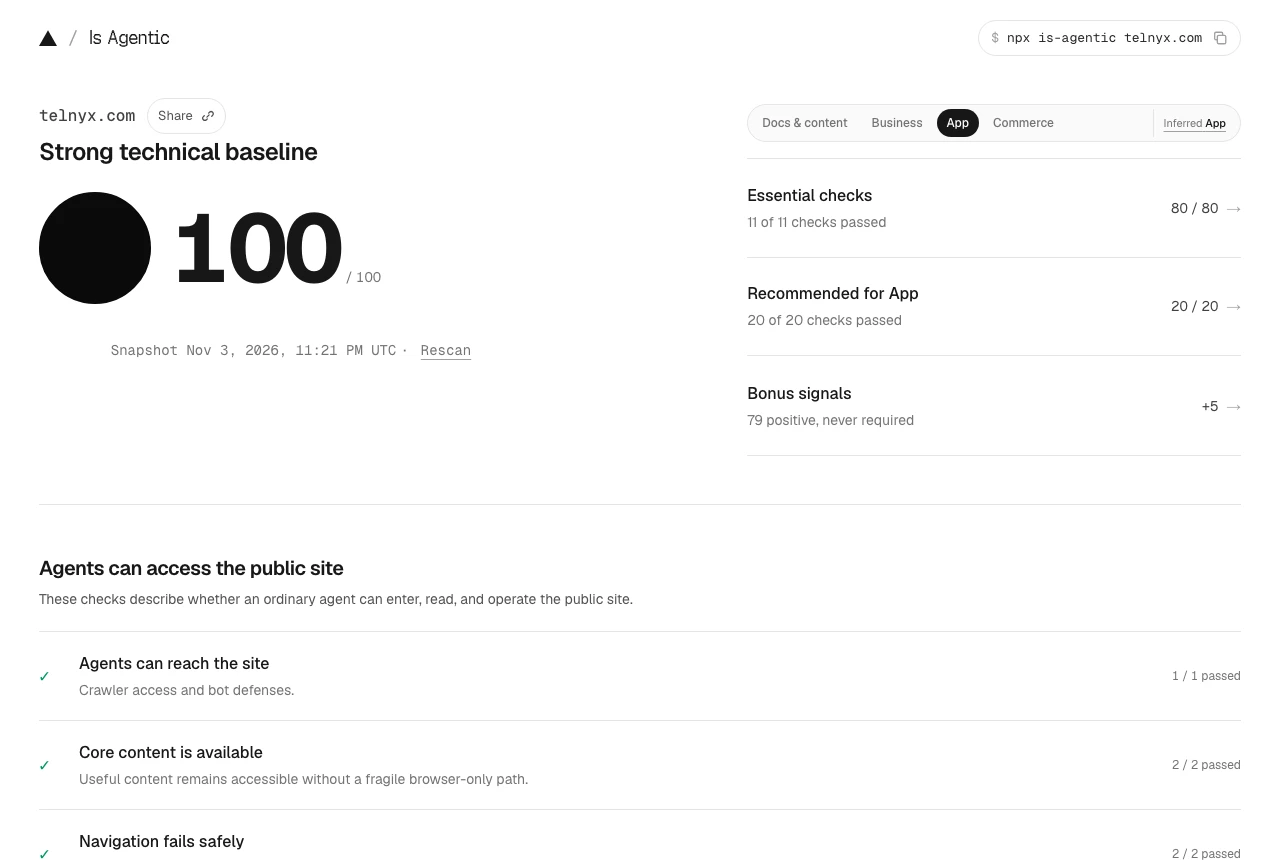
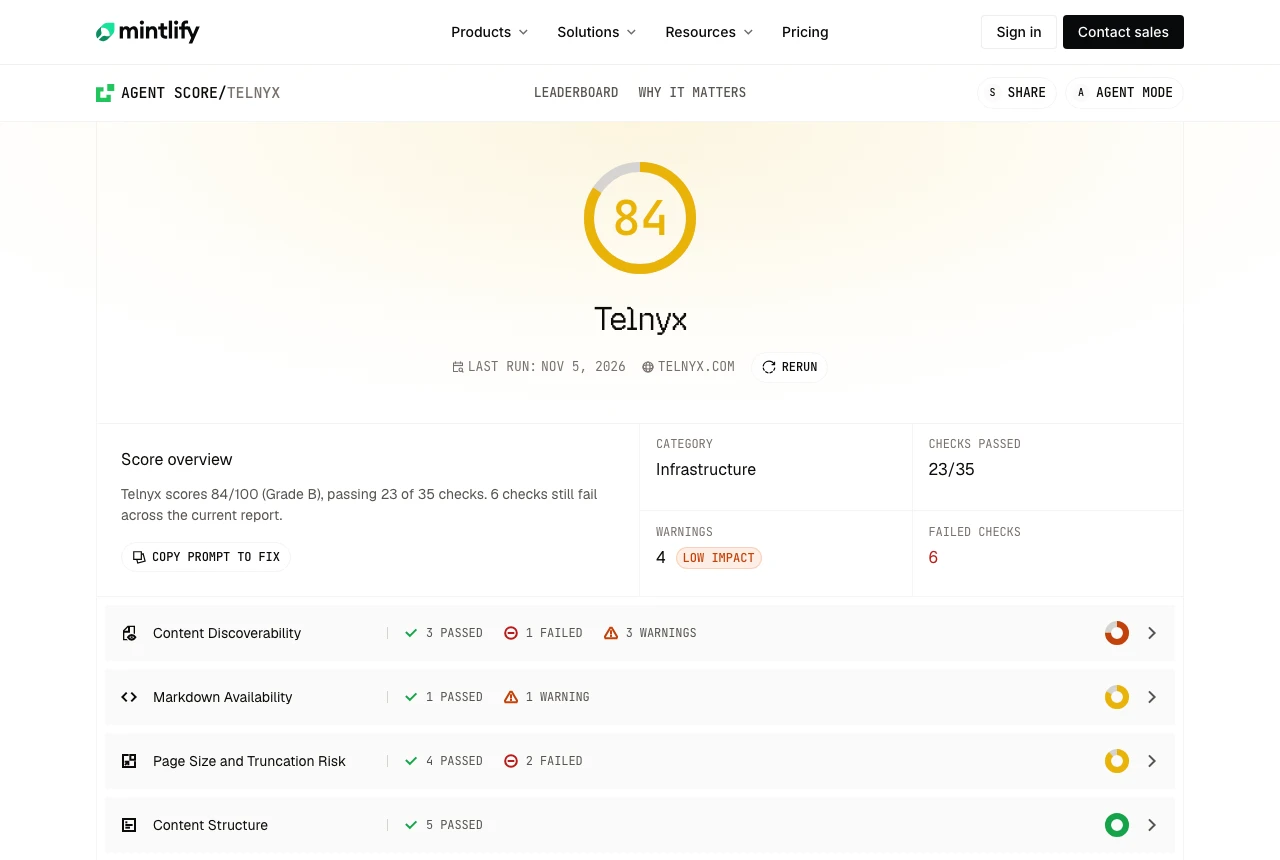
One domain, three public reports, each loaded once with a GET request and captured at 1280 pixels wide. The frames are the scanners' own pages; nothing is edited. Ora scores the domain 99, Is Agentic 100 and Mintlify 84, on three different scales and checks, which is what the score explainer is about.
Sources
- ora.ai/api/checks. https://ora.ai/api/checks, read 2026-11-05.
- ora.ai/llms.txt. https://ora.ai/llms.txt, read 2026-11-05.
- ora.ai/blog. https://ora.ai/blog, read 2026-11-05.
- ora.ai/api/stats. https://ora.ai/api/stats, read 2026-11-05.
- ora.ai/skill.md. https://ora.ai/skill.md, read 2026-11-05.
- ora.ai/api/openapi.json. https://ora.ai/api/openapi.json, read 2026-11-05.
- ora.ai/blog/introducing-deep-scan. https://ora.ai/blog/introducing-deep-scan, read 2026-11-05.
- ora.ai. https://ora.ai/, read 2026-11-05.
- agentready.org/llms.txt. https://agentready.org/llms.txt, read 2026-11-05.
- ora.ai/methodology. https://ora.ai/methodology, read 2026-11-05.
- mintlify.com/score/telnyx.com. https://www.mintlify.com/score/telnyx.com, read 2026-11-05.
- is-agentic.com/scan/telnyx.com. https://is-agentic.com/scan/telnyx.com, read 2026-11-05.
- ora.ai/score/telnyx.com. https://ora.ai/score/telnyx.com, read 2026-11-05.
Last reviewed 2026-11-05